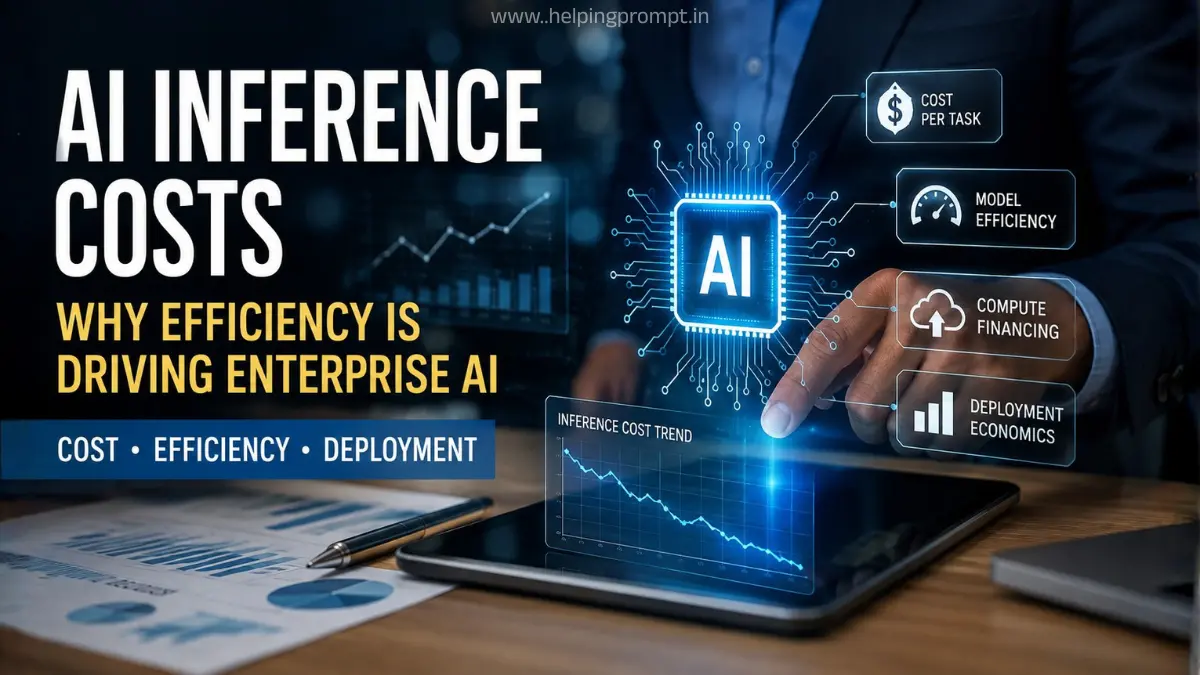
AI Inference Costs: Why Efficiency Is Driving Enterprise AI
AI inference costs are becoming a bigger boardroom issue as enterprises move AI from pilots into production. The latest pricing moves show why. DeepSeek is raising API prices for its V4 models from August 17, with peak and off-peak rates. Meanwhile, cheaper models and more efficient hardware are pushing costs down elsewhere. As a result, companies are no longer asking which model tops a benchmark.
They are asking a harder question: How much does each useful business task actually cost?
QUICK SUMMARY
- Token pricing is only the starting point: Real AI costs include retries, tools, infrastructure and operations.
- Model efficiency matters more: Smaller and specialised models can deliver better economics for routine workloads.
- Production readiness is the new test: Enterprises increasingly measure cost per task, latency, reliability and ROI.
HOW TO
- How to calculate AI inference costs?
Measure input and output tokens, model calls, infrastructure and operational overhead. Then divide the total expense by successful completed tasks.
- How to improve model efficiency?
Route simple workloads to smaller models and reserve larger models for complex reasoning. Also optimise prompts, caching and inference infrastructure.
- How to prepare an AI deployment budget?
Estimate realistic workload volume and calculate cost per task. Then include infrastructure, monitoring, security, integration and potential pricing changes.
AI Inference Costs Are Becoming a Core Enterprise Metric
For years, AI evaluations focused heavily on benchmark scores. Now, finance teams want a clearer picture. They need to know the cost of producing a useful outcome. That means measuring tokens, latency, infrastructure and workload volume together. Recent industry analysis shows inference is becoming a major long-term AI expense. Therefore, the cheapest model on a price sheet may not deliver the cheapest business result.
Token Pricing Does Not Tell the Full Story
A model’s advertised token price can look attractive. However, production workloads often involve multiple model calls. Agents may use tools, retrieve documents, retry requests or generate longer responses. Consequently, one customer task can consume far more tokens than expected. Enterprise teams should calculate the complete cost per task instead of relying only on input and output rates. This approach also makes budgeting more realistic.
Model Efficiency Is Changing Deployment Choices
Efficiency is becoming a competitive advantage across the AI stack. Smaller models can handle classification, extraction and routine support tasks. Larger reasoning models can then handle complex decisions. This model-routing approach can reduce unnecessary compute consumption. NVIDIA, for example, has highlighted model-routing software designed to balance cost, latency and performance. As a result, enterprises can build systems around several models instead of one expensive model.
Cost Per Task Beats Cost Per Token
Consider an AI support system handling thousands of customer queries. A cheaper model may need multiple attempts to produce an acceptable answer. A more expensive model could complete the same task in one call. Therefore, comparing token prices alone can create the wrong conclusion. The better metric is cost per successful task. Enterprises should also track accuracy, latency, retries and human intervention before approving large-scale deployment.
Compute Financing Is Becoming a Strategic Issue
AI deployment economics also extend beyond API bills. Companies running private infrastructure must consider GPUs, networking, power, cooling and utilisation. Underused hardware can quickly weaken the business case. At the same time, demand for inference infrastructure is expanding. IBM and Together AI recently announced a $240 million agreement for a large Nvidia-powered inference cluster. Thus, financing and infrastructure planning are becoming part of AI strategy.
Production Readiness Requires More Than Model Quality
An impressive demonstration does not guarantee a successful enterprise deployment. Production systems need predictable latency, security, monitoring and reliable integrations. They also need clear governance and cost controls. For Indian businesses, currency exposure and cloud-region decisions can add another budgeting layer. Therefore, technology leaders should test AI with real workloads before committing to large infrastructure investments. The goal is predictable economics, not impressive demo performance.
Pricing Volatility Could Change AI Budgets Quickly
Recent pricing changes underline another challenge: AI costs can move quickly. DeepSeek’s upcoming V4 pricing changes include increases ranging from 50% to 1,100%, depending on model, token type and usage period. Meanwhile, other providers have cut prices on selected models. This creates both opportunities and risks. Enterprises should avoid designing budgets around one provider or one model. Flexible architectures can make switching easier when economics change.
Enterprise AI Is Moving Toward Cost-Aware Architectures
The next phase of AI adoption will likely focus on efficiency as much as intelligence. Companies can combine smaller models, caching, batching and intelligent routing for routine workloads. Sensitive applications may justify dedicated infrastructure, while unpredictable demand can favour APIs. The right choice depends on utilisation and workload patterns. Ultimately, deployment economics should connect technical performance with measurable business value. That is the real shift beyond benchmarks.
PRO TIPS
- Track cost per successful task, not only dollars per million tokens.
- Use model routing so expensive reasoning models handle only complex workloads.
- Review infrastructure utilisation before choosing self-hosting over managed AI APIs.
CONCLUSION
AI inference costs are becoming a central factor in enterprise technology decisions. Token prices still matter, but they no longer tell the whole story. Businesses must consider model efficiency, infrastructure, latency, reliability and workload volume together. Recent pricing changes from major AI providers show how quickly deployment economics can shift.
The winners may not be companies using the most powerful model. Instead, they could be organisations that produce useful outcomes at predictable costs. As AI moves deeper into production, cost per task will become an increasingly important KPI. Staying updated on pricing, infrastructure and model efficiency will therefore be essential for technology leaders.
FAQs
AI inference costs are the expenses involved when a deployed AI model processes requests and generates outputs. They include compute, tokens and operational costs.
Cost per task measures the actual expense of completing a business outcome. It can include retries, tools, multiple model calls and human intervention.
Companies can use smaller models, caching, batching, model routing and efficient infrastructure. The best approach depends on workload volume and latency needs.